MechAudit
A domain-bounded CLI and benchmark that independently recomputes mechanics and flags failure modes in LLM-generated engineering calculations.
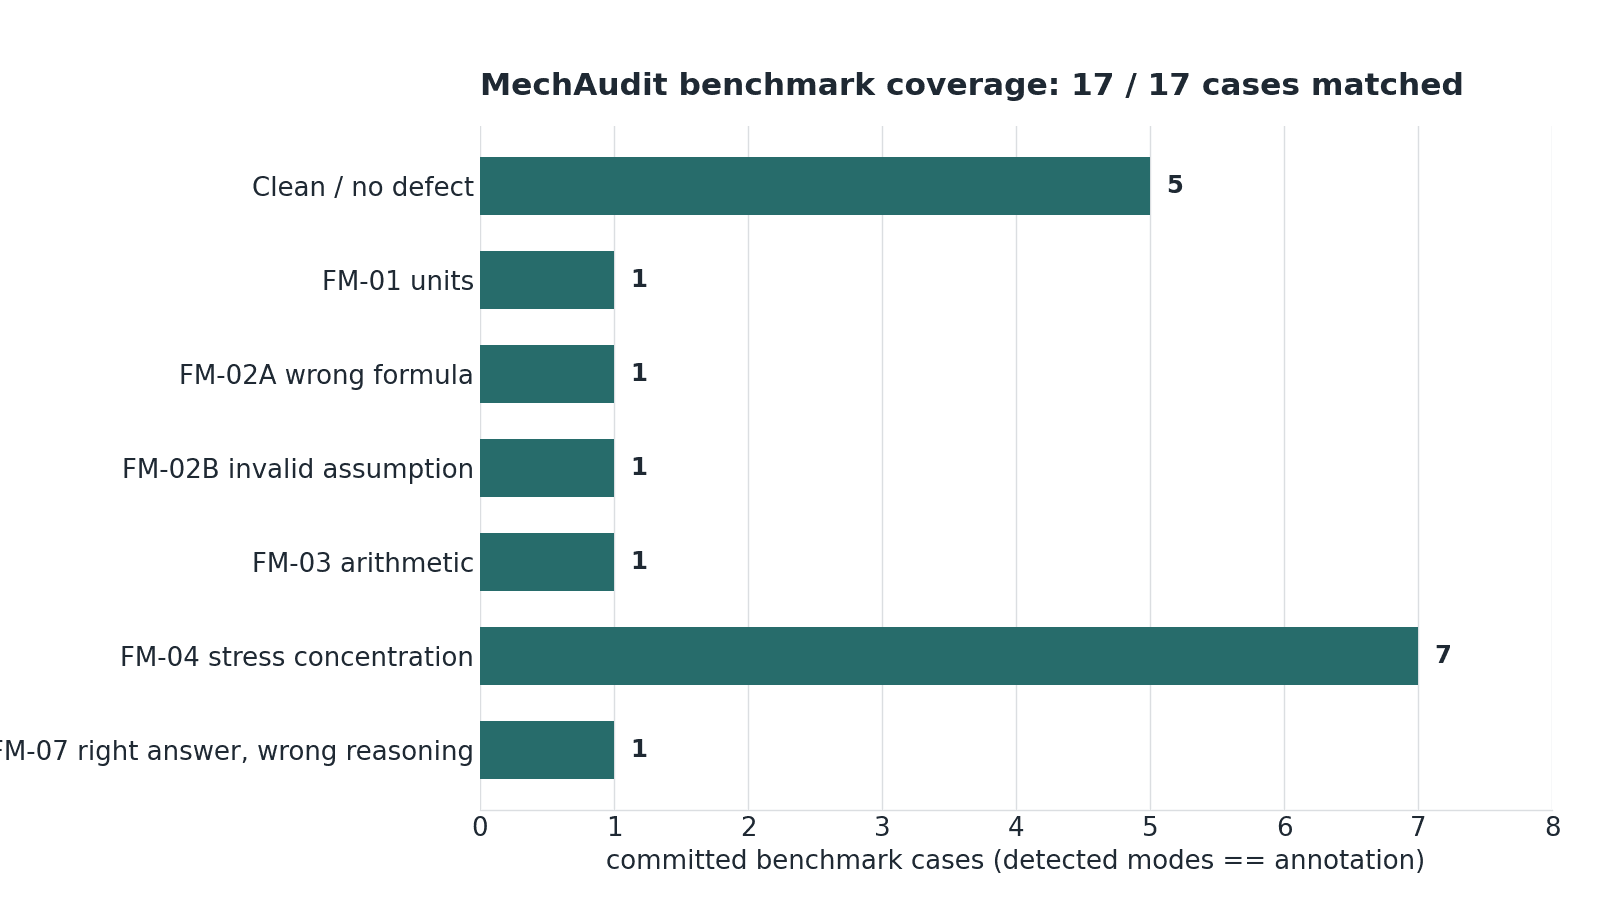
Result. Matched annotated failure modes on 17/17 committed cases across five models by independently recomputing mechanics under a six-category taxonomy.
MechAudit loads a structured benchmark case, independently recomputes supported mechanics quantities, extracts the model's reported work, and returns detected failure modes—then compares that set with the case annotation so verifier regressions fail CI. It is a domain-bounded checker, not a general proof checker or a benchmark of overall model capability.
| Category | AI / Software |
|---|---|
| Timeline | 2026 |
| Status | Complete |
| Evidence | Hash-verified benchmark |
| Role | Verifier design, failure taxonomy, independent recomputation checks, provenance-tracked benchmark capture, CLI, and CI gating |
| Tools | Python, pytest, LLM APIs |
| Links | RepositoryBenchmark results |
problem
My contribution. Built the schema/unit loader, independent calculation and answer-extraction paths, domain checks, failure taxonomy, provenance-tracked capture harness, Markdown audit report, and CI gate.
LLMs produce plausible-looking mechanical-engineering calculations with unit slips, wrong governing formulas, invalid thin-wall assumptions, arithmetic errors, and correct answers reached by incorrect reasoning. A useful verifier must recompute the physics independently and be explicit about the narrow domain it actually covers.
constraints
- Recompute supported quantities independently rather than trusting the model's arithmetic.
- Treat every benchmark case as a hash-verified capture with recorded provenance (elicited versus organic).
- Report only within the covered domain: thin-wall pressure vessels, axial stress, cantilever controls, and finite-width stress concentration.
- Verifier regressions must fail CI against the committed annotation set.
design evolution
Iterations, issues, and fixes, recorded in the order they happened.
| Revision | Failure mode | Design change | Result |
|---|---|---|---|
| Failure taxonomy | “Wrong answer” is too coarse to test a verifier against. | Defined FM-01 units, FM-02A/B formula and assumption, FM-03 arithmetic, FM-04 stress concentration, and FM-07 right-answer/wrong-reasoning. | Each case annotates specific expected failure modes. |
| Independent recomputation | Trusting the model's stated number only re-grades its own claim. | Recompute mechanics from the inputs and compare against the model's extracted reported answer. | Detected modes are computed by the checker, not read from the model. |
| Provenance and CI gate | Elicited and organic captures are different evidence classes. | Hash-verified captures with recorded provenance and a detected-equals-expected gate in CI. | 17 of 17 committed cases match; 2 skipped. |
results
Each committed case pairs an LLM calculation capture with an annotation of expected failure modes; CI passes only when MechAudit's independently computed detected modes equal that annotation.
The current domain covers thin-wall pressure vessels, axial stress, cantilever controls, and finite-width stress concentration across five models.
Scope note. Detected modes match annotations on committed elicited captures. This measures the verifier against a bounded benchmark, not overall model capability, and does not yet include organic “wild” failures captured during real engineering work.
lessons
- A failure taxonomy makes verification a checkable detection task instead of a vague judgment.
- Recomputing the physics independently is the only reliable way to catch a correct-looking wrong answer.
- Elicited and organic captures are different evidence classes and must be labeled as such.
gallery